The idea of creating a machine capable of thinking and making decisions like a human did not begin with the advent of modern computers; its roots date back thousands of years. Throughout human history, many philosophers, thinkers, and scientists have sought to understand the questions: "What is intelligence?" and "Can intelligence be synthesized?" These inquiries laid the foundational concepts that eventually led to the emergence of artificial intelligence (AI).
In ancient Greece, philosophers such as Plato and Aristotle placed great emphasis on logic, structured thought, and methods of acquiring knowledge. Aristotle, in particular, developed the first formal logical system, establishing the rules of logical deduction (Syllogism). While these works did not create AI directly, they established the foundational principle that human thought could be described through defined rules and principles.
During the Middle Ages and the early modern era, mathematicians and philosophers sought to develop logic and mathematics systematically. In the seventeenth century, Gottfried Wilhelm Leibniz proposed a universal language for logic and processing ideas. He believed that if all thought could be translated into mathematical laws, future computing devices could solve problems mathematically. Although impracticable at the time, this concept served as an intellectual bedrock for AI.
In the nineteenth century, significant progress occurred in computing and automation. Charles Babbage designed the Analytical Engine, which possessed many core features of modern computers, such as memory, a processing unit, and programmability. Although its construction was never completed, historians widely recognize it as the first design for a general-purpose computer.
During the same era, Ada Lovelace—regarded as the world's first computer programmer—made a profound observation. She predicted that future computers would not merely calculate numbers, but could also process music, images, and diverse formats of information. This forward-looking insight later held immense significance in the development of AI.
In the early twentieth century, the evolution of formal logic and mathematics accelerated dramatically. George Boole's work on Boolean logic, followed by the research of Gottlob Frege, Bertrand Russell, and Alfred North Whitehead, established a solid foundation for mathematical logic. These contributions demonstrated that certain aspects of human thought could be formalized through symbolic rules and executed by a machine.
The greatest turning point in this phase came through the work of Alan Turing. In 1936, in his landmark paper On Computable Numbers, with an Application to the Entscheidungsproblem, Turing introduced the "Turing Machine" model. He showed that any mathematical computation, if formally defined, could be executed by a universal machine. This theoretical concept forms the bedrock of computer science and AI.
Following World War II, the development of electronic computers created new opportunities to implement these theories. In 1950, Turing published Computing Machinery and Intelligence, posing the famous question: "Can machines think?" He also proposed the benchmark now known as the "Turing Test" to evaluate whether a computer system could exhibit conversational behavior indistinguishable from a human.
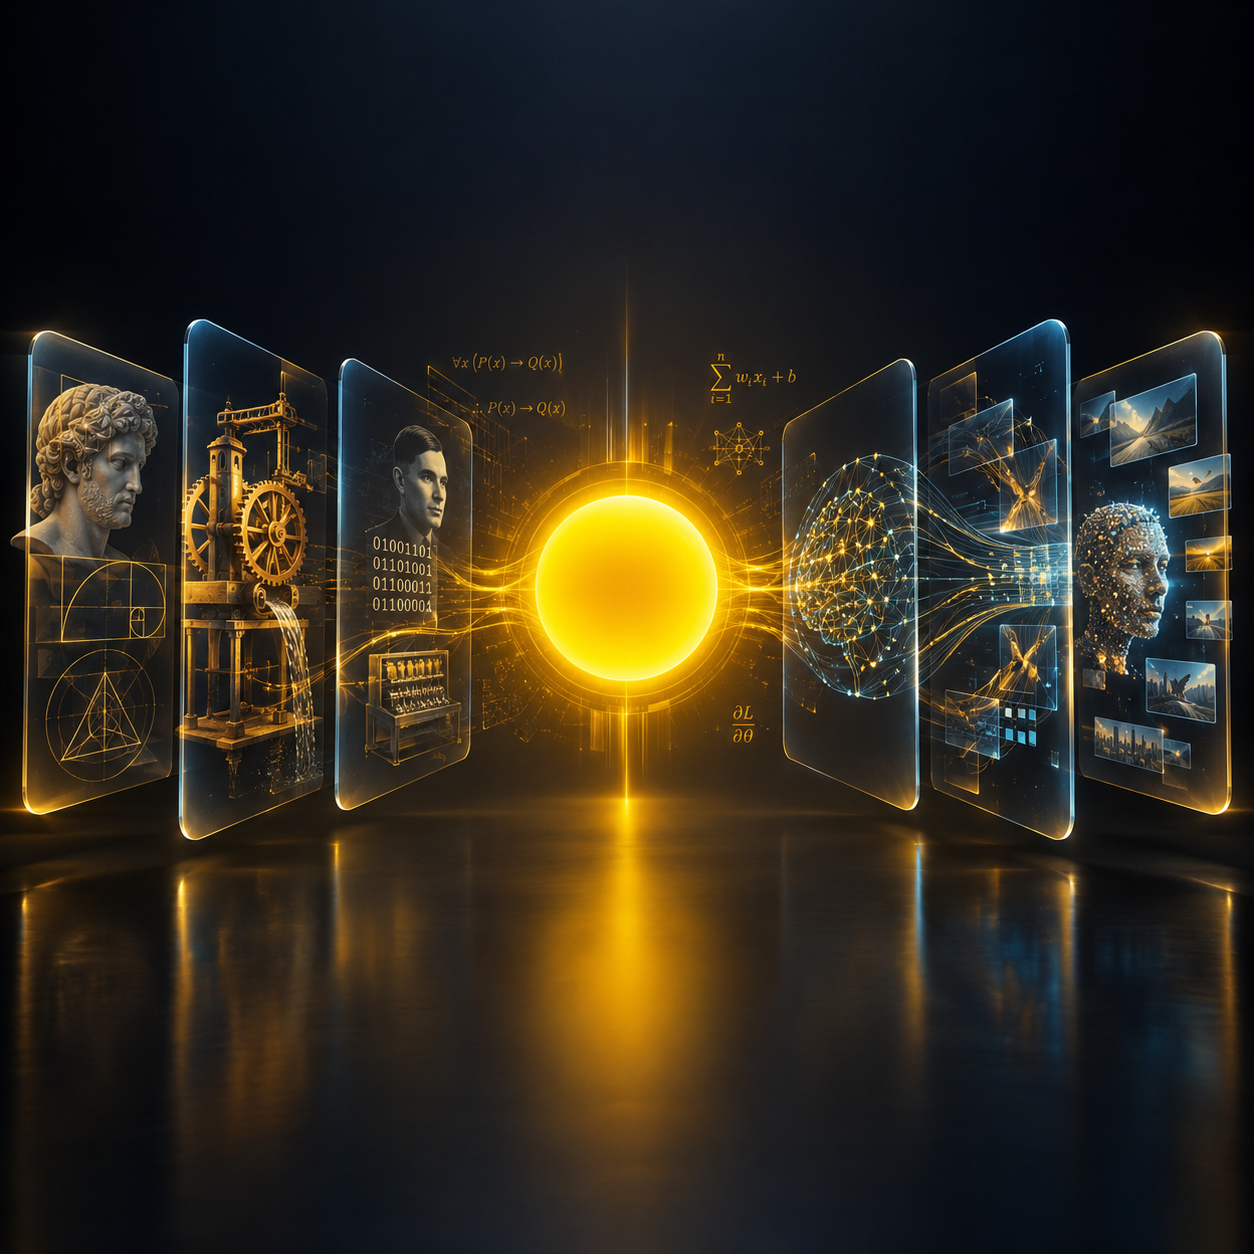
These accumulated advancements—from ancient Greek logic and Leibnizian mathematics to Babbage’s engine, Lovelace’s vision, and Turing’s theoretical formulations—provided the scientific and intellectual foundation for AI. This groundwork culminated in 1956 at the Dartmouth Conference, where artificial intelligence was formally established as an independent scientific discipline, inaugurating a new era in technological history.
Ismail al-Jazari and Automata
Centuries before the formal birth of AI, efforts to build automatic devices and self-operating systems laid a critical foundation for robotics and mechanical engineering. One of the most prominent pioneers in this field was Badi' al-Zaman Abu al-'Izz Ismail ibn al-Razzaz al-Jazari (1136–1206 AD). Al-Jazari flourished in the city of Amed (Diyarbakir) in Northern Kurdistan, serving for nearly fifty years as the chief engineer at the court of the Artuqid rulers.
In 1206 AD, al-Jazari completed his famous manuscript, The Book of Knowledge of Ingenious Mechanical Devices. This work is considered one of the most important historical treatises on mechanical engineering, detailing approximately 50 mechanical devices and systems complete with illustrations, diagrams, and precise explanations. His inventions included complex water clocks, double-acting pumps, automated servants, automated hand-washing mechanisms, and mechanical musical bands—all operating automatically through water power, gravity, and cam mechanisms.
Many technology historians consider al-Jazari one of the fathers of mechanical engineering and automation. The engineering principles he developed exerted a lasting influence on robotics and automated systems. Although his mechanisms lacked artificial intelligence in the modern sense—possessing no capacity for learning, decision-making, or autonomous behavior—his inventive work represents one of the earliest and most vital historical milestones toward humanoid automata and self-operating machines.
Alan Turing and the Turing Test
Alan Mathison Turing (1912–1954) is widely regarded as a foundational figure in computer science and artificial intelligence. His research provided not only theoretical frameworks for computing, but also a paradigm shift in evaluating machine capabilities against human intelligence. Additionally, Turing played a pivotal role during World War II in breaking the German Enigma code, an achievement that profoundly influenced the Allied victory and the development of modern computing.
The Turing Machine Model and Theoretical Computing
In 1936, Turing published his seminal paper, On Computable Numbers, with an Application to the Entscheidungsproblem, introducing the theoretical construct known as the "Turing Machine."
This model was not a physical device, but a mathematical abstraction demonstrating how any structured logical process could be executed through a finite sequence of step-by-step instructions. Its significance lay in proving that any problem describable via an algorithm could be solved by a universal machine. This insight became the foundational theory for all modern computers and remains central to theoretical computer science.
"Can Machines Think?"
In 1950, Turing published another influential paper, Computing Machinery and Intelligence, in the journal Mind. It opened with a deceptively simple question: "Can machines think?"
Turing argued that the word "think" was too philosophically ambiguous. He proposed replacing the general question with a practical operational test to evaluate the behavioral output of computer systems.
The Turing Test
Originally termed the "Imitation Game," this procedure became known in scientific circles as the "Turing Test." The setup involves three primary entities:
A human participant.
A computer or AI system attempting to imitate human behavior.
A human judge situated in a separate room, unaware of which entity is the human and which is the machine.
The judge communicates with both subjects solely through text-based messaging. If, at the conclusion of the evaluation, the judge cannot reliably distinguish the machine from the human, the machine is said to have passed the test.
Key Note: The test does not aim to prove that the machine possesses consciousness or sentience; it measures only whether its linguistic and conversational behavior mimics that of a human to a convincing degree.
Impact on the Development of AI
The Turing Test became one of the most influential concepts in the history of AI, introducing an empirical benchmark for evaluating intelligent systems. This perspective heavily influenced post-1950 research and served as a major catalyst for developing conversational agents (chatbots), question-answering systems, and later, Large Language Models (LLMs).
In the twenty-first century, with the rise of advanced chatbots and LLMs, discussions surrounding the Turing Test have re-emerged. Certain modern systems can convince users in brief exchanges that they are conversing with a human. However, most researchers agree that passing the test alone does not constitute proof of General Intelligence (AGI) or consciousness, as a system can replicate human-like outputs without genuine understanding, intent, or self-awareness.
Criticisms and Limitations
Despite its historical weight, the Turing Test has faced significant criticism. For instance, philosopher John Searle formulated the "Chinese Room" thought experiment to demonstrate that a system can manipulate symbols according to formal rules without possessing any actual understanding of their semantic meaning. Furthermore, many researchers argue that human intelligence extends far beyond natural language processing to include embodied learning, emotional processing, creativity, multi-modal decision-making, and real-world interaction.
The Dartmouth Conference and the Formal Birth of AI
Most historians and computer scientists mark the year 1956 as the official founding of Artificial Intelligence as a distinct field. During the summer of that year, a research gathering was held at Dartmouth College in New Hampshire, USA, known as the Dartmouth Summer Research Project on Artificial Intelligence.
This conference represented the first organized effort to construct an independent scientific discipline dedicated to researching how to create systems capable of displaying intelligent behavior.
Project Origins and Pioneers
The conference was proposed by John McCarthy, later dubbed a "Father of AI." He co-authored the proposal alongside Marvin Minsky, Nathaniel Rochester of IBM, and Claude Shannon, the founder of Information Theory.
The proposal famously stated:
"Every aspect of learning or any other feature of intelligence can in principle be so precisely described that a machine can be made to simulate it."
This assertion served as a foundational premise for researchers of that era, who believed human cognition could be fully formalized into rules, algorithms, and computational processes.
Birth of the Term "Artificial Intelligence"
A primary historical milestone of the Dartmouth Conference was John McCarthy's formal coining of the term Artificial Intelligence. Prior to this, research in the domain operated under varied nomenclature, such as Cybernetics, Automata Theory, or Complex Information Processing.
Selecting this new terminology was a strategic move by McCarthy to delineate the discipline from adjacent fields and establish its independent identity. Thus, 1956 marked not merely a conference, but the official birth of a new scientific domain.
Primary Objectives of the Conference
Researchers at Dartmouth optimistically anticipated that the core challenges of human intelligence could be solved within a few years. Their main objectives included:
Developing automated machine learning systems.
Natural Language Processing and understanding.
Formulating problem-solving and decision-making mechanisms.
Modeling logical reasoning.
Developing computer vision and object recognition capacities.
Constructing a machine capable of replicating human behavior.
While researchers envisioned rapid achievements, subsequent events demonstrated that human cognition was vastly more complex than initially modeled.
Impact and Academic Support
Although the Dartmouth Conference did not immediately yield major technical deliverables, its impact on directing computer science was profound. Following the event, major universities established dedicated AI laboratories, including MIT, Stanford University, and Carnegie Mellon University.
Concurrently, the US government and agencies such as DARPA provided substantial funding for research. This capital influx became the primary driver for early intelligent programs and machine learning methodologies.
Early Milestones (1950s–1960s)
In the late 1950s and early 1960s, several pioneering projects emerged:
Logic Theorist (1956): Developed by Allen Newell and Herbert A. Simon, often cited as the first AI program, capable of proving mathematical theorems.
General Problem Solver (GPS): A pioneer effort to build a domain-independent problem-solving framework.
LISP Programming Language (1958): Invented by John McCarthy, which remained the primary language for AI research worldwide for several decades.
These accomplishments demonstrated that computers could successfully execute formal logical operations.
AI Winters
Following the initial enthusiasm of the late 1950s and early 1960s, researchers and funding bodies believed machines would soon master human cognitive tasks. However, these expectations outpaced the computational realities of the era. The resulting gap between promise and performance led to severe contractions in funding, public trust, and research activity—periods historically designated as "AI Winters."
An "AI Winter" refers to a historical period marked by sharp declines in funding and interest due to unfulfilled expectations. These periods forced the discipline to re-examine its underlying paradigms and theoretical assumptions.
The First AI Winter (1970s)
The first AI winter emerged in the late 1960s and early 1970s. While early systems like Logic Theorist, GPS, and ELIZA had captured media attention, their practical capabilities were narrowly constrained. Most operated only within stylized, laboratory environments ("toy domains") and failed when applied to complex, real-world problems.
Perceptrons (1969): Marvin Minsky and Seymour Papert published the book Perceptrons, mathematically demonstrating the limitations of single-layer artificial neural networks. Although their critique was scientifically precise, funding agencies interpreted it as proof that neural network research was a dead end, stalling neural network funding for nearly two decades.
The Lighthill Report (1973): Prepared by mathematician Sir James Lighthill for the UK government, this strategic report strongly criticized AI's lack of practical achievements. Consequently, the British government drastically reduced AI research funding, influencing international funding decisions.
Temporary Revival (1980s)
In the 1980s, interest in AI revived, driven by the commercial success of Expert Systems. These systems encoded the knowledge and rules of human experts in specific domains to solve complex problems. Major corporations such as Digital Equipment Corporation and IBM invested heavily in the field.
Concurrently, the Japanese government launched its Fifth Generation Computer Systems (FGCS) project, aiming to build parallel-processing supercomputers dedicated to AI tasks. These initiatives renewed optimism and commercial funding.
The Second AI Winter (Late 1980s–Early 1990s)
Despite renewed investment, AI encountered another severe setback in the late 1980s. Expert systems proved expensive to build, difficult to maintain, fragile under changing environments, and limited in scalability.
Simultaneously, the rapid rise of general-purpose Personal Computers (PCs) rendered specialized AI hardware (such as Lisp machines) obsolete and cost-ineffective. As commercial AI ventures failed, funding collapsed, entering the second major AI Winter.
Primary Drivers of AI Winters
Overpromised Expectations: Unrealistic timelines regarding the achievement of human-level intelligence.
Hardware Limitations: Insufficient processing power and memory capacity relative to task complexity.
Data Scarcity: Absence of large, structured datasets required to train complex models.
Algorithmic Constraints: Reliance on primitive rule-based paradigms lacking statistical adaptability.
Laboratory-to-Real-World Gap: System failure when moving from controlled environments to noisy, real-world settings.
Investor Disillusionment: Withdrawal of government and corporate capital following missed milestones.
The Rise of Machine Learning
Following the AI Winters, researchers shifted away from classical rule-based approaches (Rule-Based Systems). Hand-coding every rule and edge-case proved intractable for complex, real-world problems characterized by dynamic environments and noisy data.
This realization catalyzed a paradigm shift toward Machine Learning (ML). Rather than relying solely on hardcoded logic, computer systems were designed to learn patterns directly from data.
Hardware Advances and Computational Scaling
The advancement of machine learning was driven by significant improvements in computer hardware. During the 1990s and early 2000s, rapid developments in Central Processing Units (CPUs) by companies like Intel and AMD increased execution speeds, enabling the training of more complex statistical models on larger datasets.
Definition of Machine Learning
Machine Learning is a core branch of AI focused on developing algorithms that automatically infer patterns from data to make predictions or decisions without being explicitly programmed for every scenario.
Arthur Samuel, a pioneer in the field, defined machine learning in 1959 as:
"The field of study that gives computers the ability to learn without being explicitly programmed."
Key Drivers of Machine Learning's Growth
Digital Data Explosion: The proliferation of digital infrastructure led to the creation of large datasets.
Compute Infrastructure: Enhanced processing speeds and affordable hardware.
Mathematical Methodologies: Advancements in probability theory, statistics, and optimization.
Commercial Demand: Industry requirements for predictive analytics, data classification, pattern recognition, and automation.
Primary Paradigms of Machine Learning
Supervised Learning: The model is trained on labeled data where input features are paired with ground-truth outputs. The objective is to learn a mapping function to predict labels for unseen inputs.
Examples: Real estate price estimation, spam filtering, and medical image classification.
Unsupervised Learning: The algorithm receives unlabeled data and attempts to discover underlying structures, clusters, or patterns independently.
Examples: Customer segmentation, anomaly detection, and dimensionality reduction.
Reinforcement Learning: An agent learns by interacting with an environment through trial and error, receiving rewards for optimal actions and penalties for suboptimal ones. Over time, it optimizes a strategy (policy) to maximize cumulative rewards.
Examples: Game playing (e.g., Go, chess), robotics control, and autonomous navigation.
Algorithmic Innovations and Neural Network Resurgence
During the 1990s and 2000s, algorithms such as Decision Trees, Random Forests, Support Vector Machines (SVM), Naïve Bayes, and k-Nearest Neighbors (k-NN) gained widespread adoption across finance, medicine, and NLP.
Concurrently, research into artificial neural networks resumed. The popularization of the backpropagation algorithm in the late 1980s by Geoffrey Hinton, David Rumelhart, and Ronald Williams provided a mathematically viable method for training multi-layer neural networks, laying the foundation for Deep Learning.
The Advent of Big Data and GPUs
In the early twenty-first century, the expansion of the internet, mobile devices, and digital services led to the generation of massive datasets—a phenomenon termed Big Data.
Because statistical ML models scale effectively with increased data volume, Big Data provided the necessary training material. Concurrently, the transition from CPUs to Graphics Processing Units (GPUs) and parallel computing frameworks enabled the execution of large matrix operations in parallel, reducing model training times from months to days.
Practical Impact of Machine Learning
Machine Learning transformed AI applications across various domains:
Recommendation systems (e.g., Netflix, Spotify).
Automated language translation.
Speech recognition and computer vision.
Predictive diagnostics in healthcare.
Automated fraud detection and email filtering.
Crucially, ML served as the bridge to Deep Learning and Generative AI.
The Deep Learning Revolution
Deep Learning represents a major turning point in artificial intelligence. Although theoretical concepts of Artificial Neural Networks (ANNs) were developed in the 1940s and 1950s, hardware constraints, data scarcity, and training difficulties limited their deployment for decades.
In the early 2010s, the convergence of Big Data, GPU hardware acceleration, and algorithmic breakthroughs enabled Deep Learning to become the primary paradigm driving AI progress.
Architectural Paradigm Shift: CPU to GPU Acceleration
A key factor in the deep learning revolution was transitioning model training workloads from CPUs to GPUs. Initially designed for rendering 3D graphics, GPUs excel at executing thousands of matrix operations simultaneously in parallel—the exact mathematical workload required by deep neural networks.
NVIDIA's release of the CUDA platform in 2006 enabled researchers to utilize GPUs for general-purpose scientific computing and neural network training. This hardware acceleration enabled the training of deep models such as AlexNet in 2012.
Principles and Architecture of Deep Learning
Deep Learning utilizes Deep Neural Networks (DNNs) consisting of multiple hidden layers. Each layer extracts progressively higher-level features from raw input data.
For instance, in an image recognition pipeline:
The initial layer detects basic edges and gradients.
Intermediate layers identify shapes and textures.
Deep layers recognize complex objects (e.g., faces, vehicles).
Unlike traditional ML, which relied on manual feature engineering, deep learning architectures automatically learn hierarchical feature representations directly from raw data.
The ImageNet Breakthrough (2012)
Many historians identify 2012 as the official beginning of the Deep Learning boom. Alex Krizhevsky, Ilya Sutskever, and Geoffrey Hinton entered a Convolutional Neural Network (CNN) named AlexNet into the ImageNet Large Scale Visual Recognition Challenge.
Trained on GPUs, AlexNet achieved a dramatic reduction in error rates compared to shallow machine learning models. This success demonstrated the efficacy of deep CNNs for visual tasks, prompting widespread investment across academia and industry.
Key Deep Learning Architectures
Convolutional Neural Networks (CNNs): Designed for spatial data processing, computer vision, and medical imaging.
Recurrent Neural Networks (RNNs): Tailored for sequential data processing, such as time-series and speech.
Long Short-Term Memory (LSTM): Specialized RNN architectures designed to capture long-range dependencies without suffering from vanishing gradients.
Transformers: Introduced in 2017, these attention-based architectures replaced recurrent models for sequential processing, forming the foundation of modern Large Language Models (LLMs) and Generative AI.
Practical Applications of Deep Learning
Computer Vision: Facial recognition, medical diagnostics, autonomous vehicle perception.
Natural Language Processing: Machine translation, automated summarization, conversational AI.
Speech Processing: Real-time voice synthesis and speech-to-text recognition.
Biomedicine: Protein folding prediction (e.g., AlphaFold) and genomic analysis.
Challenges and Limitations
Resource Intensity: Training state-of-the-art models requires massive datasets and compute infrastructure, driving up energy consumption and financial costs.
The "Black Box" Problem: Deep networks exhibit high complexity, making it difficult to interpret their internal decision-making processes. This opacity poses challenges for deployment in high-stakes domains such as healthcare, finance, and legal systems.
Generative AI and ChatGPT: The Era of Content Creation
In the late 2010s and early 2020s, AI entered a new phase known as Generative AI. Unlike classical discriminative models designed to classify or analyze existing data, generative models produce new synthetic artifacts—including text, images, audio, video, and code.
Definition of Generative AI
Generative AI refers to deep learning models trained on large datasets to infer statistical patterns, enabling them to generate novel outputs that mirror the structure of their training data rather than merely retrieving or classifying inputs.
Hardware Infrastructure and Large Language Models (LLMs)
Training generative models requires extensive computational resources, typically utilizing clusters containing thousands of specialized GPUs (e.g., NVIDIA A100 and H100) running parallelized software frameworks (such as CUDA).
Built upon Transformer architectures, Large Language Models (LLMs) are trained on hundreds of billions of text tokens. This pre-training enables them to model complex linguistic relationships, context, and reasoning tasks.
Capabilities of LLMs
Logical reasoning and question answering.
Text generation, editing, and summarization.
Multi-lingual machine translation.
Code generation, debugging, and documentation.
Assisting scientific workflows and creative tasks.
ChatGPT and Public Adoption
Developed by OpenAI, ChatGPT became a prominent application of generative AI. Built upon the GPT (Generative Pre-trained Transformer) series, its public release on November 30, 2022, led to rapid adoption across diverse user bases.
A key factor in its conversational performance was the implementation of Reinforcement Learning from Human Feedback (RLHF), a fine-tuning technique that aligns model outputs with human intent, safety guidelines, and conversational tone.
Domain Impact of Generative AI
Education: Personalized tutoring, content summarization, and instructional design.
Healthcare: Clinical documentation assistance and literature synthesis.
Software Engineering: Automated code completion, refactoring, and bug detection.
Media & Journalism: Content drafting, research assistance, and digital publishing.
Enterprise & Operations: Automated customer support, market analysis, and internal knowledge retrieval.
Creative Arts: Synthetic image generation, musical composition, and video editing.
History of Artificial Intelligence
Rebaz Ahmed
Article author